— You Are At The Archives for the SEO Tag —

Google AJAX Search Results

June 28 2010 // SEO // 2 Comments

A few months ago I wrote about how you could track keyword rank in Google Analytics. I said I’d blog about how to create ranking reports based on the new data but as I did due diligence on those reports I found something much more interesting.

AJAX Search Results Performance

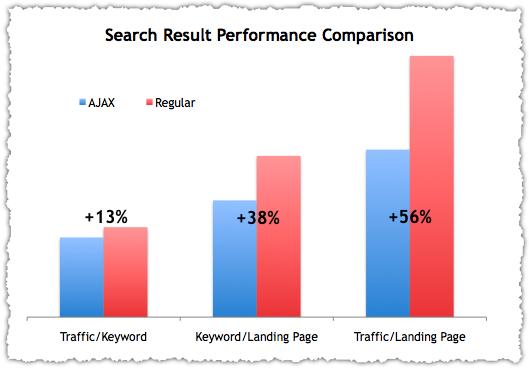
There is a profound difference in the performance of Google AJAX search results versus normal search results.
Google Search Results Comparison

Standard search results drive 13% more traffic per keyword, 38% more keywords per landing page and 56% more traffic per landing page than their AJAX counterparts.

Creating The Search Result Comparison

The Google Analytics rank hack captures a specific rank parameter present on AJAX search results. If that parameter doesn’t exist no rank is reported for that keyword. Upon implementing the GA rank hack you find that Google is serving AJAX results approximately 20% to 25% of the time. This is simply a product of looking at traffic that is reported with a rank compared to the total traffic reported in the profile.

You can also create advanced segments that include or exclude the AJAX search results by using the user defined value (Rank:) implemented in the GA rank hack. This gives you the ability to easily compare the performance of AJAX versus normal search results.

Each week I capture the amount of traffic as well as the number of keywords and landing pages that drove that traffic. I then create calculated metrics around traffic per keyword, keywords per landing page and traffic per landing page. There’s no real right or wrong number for these metrics, but it can be quite useful in trend analysis and, in this instance, for comparison analysis.

I’ve aggregated results from two large sites that come from very different verticals. Both showed similar results. I recognize that two is a small sample size so I encourage others to perform the same analysis to increase the confidence level of these results.

What’s Going On With AJAX Results?

It’s difficult to say with certainty why AJAX search results would perform so radically different than normal search results.

I first compared the Browser and OS profile for each to see if there was a distribution discrepancy. Sure enough, there is. Normal results are presented with far greater frequency (almost to exclusion) for the following:

  • Safari/Macintosh
  • Chrome/Windows
  • Firefox/Macintosh
  • Safari/iPhone
  • Safari/Android
  • Safari/iPad
  • Safari/iPod
  • Chrome/Macintosh

Yet, when I isolate Internet Explorer/Windows (sadly, the dominant combination) I see the same pattern for each result type. So while the difference in Browser and OS is interesting, it doesn’t seem to be the reason for the performance differential between AJAX and normal search results.

Could it be algorithmic? It seems far fetched to think Google would implement a different algorithm for AJAX search results. Nevertheless, lets put it down using the ‘no idea is a bad idea’ brainstorming methodology.

Perhaps it’s related to the presentation of search results. This makes a bit of sense since they are being rendered differently. But most people can’t tell the difference between the two, so I don’t think the way in which they are rendered would result in different user behavior.

But what about the intersection between algorithm and presentation? What if the implementation of Onebox, personalization or AdWords varied by type of search result? Could Google be using AJAX search results for testing purposes?

Further analysis leads me to believe this might be true.

The June Gloom Update

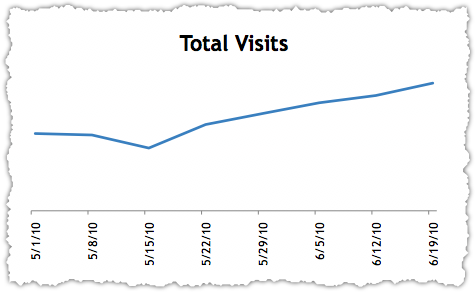
The thread of this analytic sweater began when I noted that total traffic from Google was going up but ranked traffic was going down.
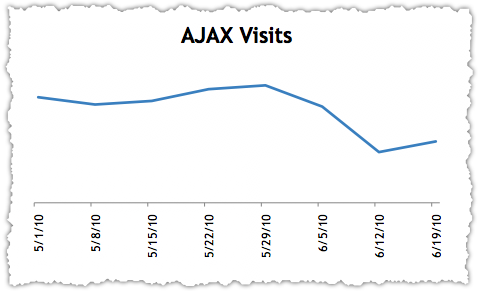
Google Total Visits

Google AJAX Visits

The opposing trend lines don’t make sense. This strange trend began around June 1st which is why I call it June Gloom.

Of course, a simple explanation could be that Google was showing fewer AJAX results. So I dug further.

Ranked Traffic on Google AJAX Results

The great thing about the Google Analytics rank hack is that you can track the trend of each position.
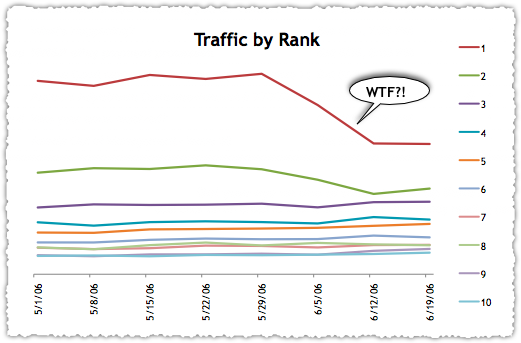
Google AJAX Traffic by Rank

The trend for keyword rank 1 and 2 dropped dramatically (~40% and ~25% respectively) while all other ranks were flat or improved during the same period. The drop in traffic from rank 1 and rank 2 far surpassed the increases in traffic from all other ranks combined. Hence, the drop in overall AJAX results traffic.

Clearly, this same pattern is not happening with normal search results. If it was, the total traffic from Google would be going down. Instead it’s going up. This also indicates that it is not about how often AJAX search is presented.

What Caused June Gloom?

Maybe the tracking parameter is broken. It could, but that would mean that it was broken on just keywords ranked first and second, and that it was only broken on those ranks some of the time. This isn’t impossible, but it certainly seems improbable. Inspection of AJAX search results didn’t turn up any missing rank parameters.

I decided to check a handful of high volume keywords which had a number 1 ranking. An advanced segment for rank 1 can quickly identify these keywords. On both sites, the top performing keywords did not show any impact from June Gloom.

I double checked this by using the new Top Queries report in Google Webmaster Tools. Downloading and comparing the weekly data, I rounded the position number and then created a pivot table to look at impressions and clicks for keywords in the first position. There was virtually no difference in impressions, clicks or click rate pre and post June Gloom.

This doesn’t mean it’s not happening, it only means that it’s not happening on the top queries. Remember, the Top Queries report is not all inclusive and it probably draws from all results – both AJAX and standard.

If top queries were unaffected, it followed that long tail keywords were being impacted by June Gloom. This could be based on keyword volume, keyword type or number of words in the query. The latter was the easiest to test.

By using the Google Analytics API we grabbed keywords that had delivered traffic at rank 1. We used an Excel function to count the number of words and then created a pivot table showing the sum of clicks by word count. We then compared the distribution of traffic by word count in a pre and post June Gloom week. The result? The distribution was virtually the same.
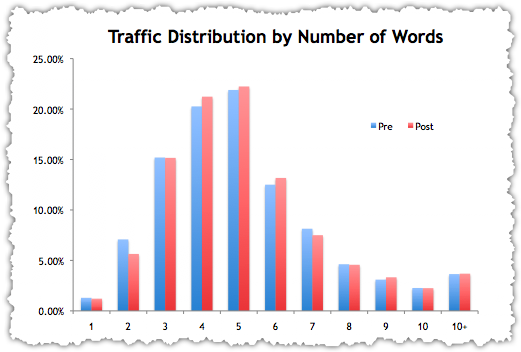
Word Count Traffic Distribution

So we can only theorize that long tail keywords based on volume or type are being impacted by June Gloom. What would do that? Greater AdWords reach? More personalization? A higher rotation of Onebox and/or 7-pack listings? Or maybe it is algorithmic. Unfortunately, we have been unable to find the smoking gun – that query or queries that present differently on each type of search result.

Or perhaps we’ve botched it – made a gross assumption or overlooked the obvious. Once again, peer review is encouraged.

Who’s this we? This is a good time to mention that my colleague Jeremy Post provided invaluable assistance in data gathering and in talking through the analysis.

June Gloom and Caffeine

These days no change in traffic can escape the Caffeine question. Strangely, there is some evidence of Caffeine in the data.

The number of landing pages driving total traffic has increased. Landing pages are up nearly 20% for standard search results and only down 3% for AJAX search results. In fact, one of the two sites saw a small increase in landing pages from AJAX results. The number of landing pages was least affected in AJAX results compared to the changes seen in traffic and keywords.

This leads me to believe that the improvements in crawl and indexation brought on by Caffeine may be adding more landing pages. However, these new landing pages haven’t yet acquired a cluster of keywords. This drives down the keywords per landing page metric. Essentially, the rate in which keywords are added is less than the rate landing pages are being added.

The difference on AJAX search results is that there were substantial keyword losses even as new landing pages were being added. June Gloom may actually have been tempered by the impact of Caffeine.

AJAX Results and June Gloom

The evidence suggests there is a difference between AJAX and normal search results. And June Gloom only serves to reinforce this theory.

SEO is supposed to be a zero sum game. One site gains traffic at the expense of another. Are other sites benefiting from AJAX results? What sites are now getting more traffic from those top two positions?

Of course, AJAX results and June Gloom could be the vehicle Google is using to test Onebox, 7-pack, personalization and universal search options. SEO is still a zero sum game … but the game board is expanding.

Are you ready?
The Best SEO Tools Not About SEO

June 22 2010 // SEO + Technology // 5 Comments

There are plenty of great blog posts about SEO tools, though you should be careful to look at a curated and updated list. Actually an SEO tool wiki would be an interesting idea. But I digress.

Instead of discussing the SEO tools I use I thought I’d share the other tools I use each and every day. Tools that have become indispensable, saving me time, energy and headaches.

Dropbox

Dropbox Logo

Sharing files can be hassle unless you have Dropbox.

Dropbox is essentially a cloud based storage system. I started using it to sync files between my laptop and desktop computers. But what Dropbox is really good for is sharing files with clients.

Email is unreliable and you often wind up spending time waiting for folks to find and download files. Dropbox lets you create a shared folder for each client where you can keep all related materials. Not only can your client find the materials, they can point internal resources to it with ease. This is particularly useful if a client uses contracted or offshore developers.

You may have to convince clients to install Dropbox. Don’t worry, the 2GB plan is free, installation is easy and the instant value it delivers will earn you quick kudos.

Adium

Adium Logo

I love Instant Messaging. Short of being on-site, this is often the best way to communicate, clarify and remove roadblocks. Email is slow and asynchronous. The phone doesn’t provide the added context of links or screen shots. IM is fast and effective. It can also be a hassle if you have clients on multiple IM platforms. Yahoo! Messenger, Google Talk, Jabber, AIM and more.

Setting up accounts with each is easy, but having every IM client up and running at once creates problems. Context switching between each platform’s UI is not trivial. The messages arrive in different ways (with different sounds) and you wind up having multiple windows begging for your attention.

That’s where Adium comes in.

Adium is a free instant messaging application for Mac OS X that can connect to AIM, MSN, Jabber, Yahoo, and more.

Adium unifies all your IM programs into one slick interface. The tabbed chat feature is particularly nice so that you don’t have a new window for each IM conversation cluttering up your monitor.

You can even combine contacts (the same person on multiple IM platforms) “so that each one represents a person, not an account.” This is nice when you don’t care how you reach them, just that you reach them. Like the phone, you don’t care who the carrier is, you just want to connect.

The good news is you can use Adium even if your friends or clients don’t. The bad news, it’s Mac only. Windows users might want to check out Trillian instead.

TinyGrab

TinyGrab Logo

If a picture is worth a thousand words, perhaps a screen shot is worth a few hundred.

Screen grabs are a vital part of the SEO process. You want to show clients what you’re seeing and how to fix it. If you’re building a presentation deck this isn’t a huge problem.

If you’re having an IM conversation about an issue (with Adium I hope), the traditional screen grab can be slow and clunky. Enter TinyGrab.

Download this tool and each time you take a screen grab it saves it to the cloud and copies a tiny URL of it to your clipboard. Then simply paste it into your conversation and you’ll be looking at the same thing in no time.

The free version of TinyGrab gives you 10 grabs a day. For a one-time fee of £10 you can upgrade to the premium version for unlimited grabs.

These tools make me more productive every day. Do you have other tools that make a difference in your daily life? Share them here.

Google’s Heisenberg Problem

June 13 2010 // SEO // 6 Comments

Google has a Heisenberg problem. In fact, all search engine algorithms likely have this problem.

Google Heisenberg Problem

The Heisenberg Uncertainty Principle

What is the Heisenberg Uncertainty Principle? The scientific version goes something like this.

The act of measuring one magnitude of a particle, be it its mass, its velocity, or its position, causes the other magnitudes to blur. This is not due to imprecise measurements. Technology is advanced enough to hypothetically yield correct measurements. The blurring of these magnitudes is a fundamental property of nature.

The quantum mechanics that go into the Heisenberg Uncertainty Principle are hard to follow. That’s probably an understatement. It is fascinating to read about the verbal jousting Heisenberg, Schrödinger and Einstein on the topic. (I’m envisioning what the discussion might look like as a series of Tweets.)

Yet, some of the mainstream interpretations you get from the Heisenberg Uncertainty Principle are “the very act of measuring something changes it” and, by proxy, that “the observer becomes part of the observed system”.

These two interpretations can be applied to Google’s observation of the Internet.

Google Changes the System

Observer from Fringe

Not only does Google observe and measure the Internet, they communicate about what they’re measuring. Perhaps quantum theorists (and those looking at comments on YouTube) would disagree with me, but the difference is also that the Internet is made up of real sentience. Because of this, the reaction to observation and measurement may be magnified and cause more ‘blur’.

In ancient SEO times, meta keywords were used in the algorithm. But the measurement of that signal caused a fundamental change in the use of meta keywords. This is a bit different than the true version of the Heisenberg Uncertainty Principle where measuring one signal would cause the others to blur. In this case, it’s the measurement of the signal that causes it and the system to blur.

Heisenberg and the Link Graph

Today the algorithm relies heavily on the link graph. Trust and authority are assigned based on the quality, quantity, location and diversity of links between sites. Google has been observing and measuring this for some time. The result? The act of linking has blurred.

The very act of measuring the link graph has changed the link graph.

In an unmeasured system, links might still be created organically and for the sole purpose of attribution or navigation. But the measured system has reacted and links are not created organically. The purpose for a link may be, in fact, to ensure measurement by the observer.

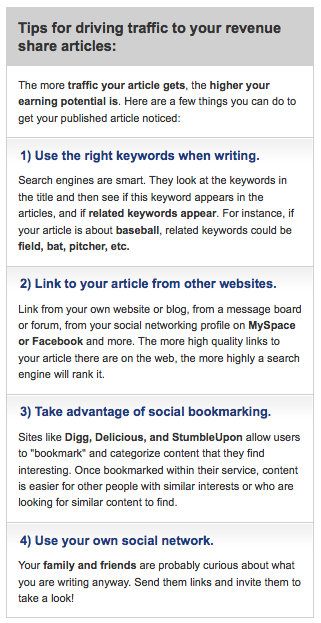
Nowhere is this more clear than Demand Media’s tips to driving traffic.

Demand Studios Traffic Tips

Clearly, the observer has become part of the observed system.

Social Search Won’t Help

There are those who believe that moving from document based measurement to people based measurement will solve algorithmic problems. I disagree.

In fact, the people web (aka social search) might be more prone to blur than the document web. Documents can’t, in and of themselves, alter their behavior. The raft of content produced won’t simply change on it’s own, people have to do that. And that’s precisely the problem with a people based algorithm.

Think links, social mentions and other Internet gestures are perverted by measurement now? Just think how they’d change if the measurement really were on people. The innate behavior of people on the web would change, as would their relation to documents. Do I have to mention Dr. House’s favorite mantra?

No, social search won’t help. Is it another signal? Sure. But it’s a signal that seems destined to produce a higher amount of blur.

Does Google Measure Blur?

Does Google have an attribute (meta data) attached to a signal that determines the rate or velocity of blur? I have no idea. But those folks at Google are pretty dang smart. And clearly something like that is going on since signals have gone in and out of favor over time.

At SMX Advanced 2010, Matt Cutts made it clear that the May Day algorithm change was made, primarily, to combat content farms. These content farms are a form of blur. The question is what type of signals did they trace the blur back to? Were they content based signals (e.g. – quality of content based on advanced natural language processing) or link based signals?

Does Google realize they are, inadvertently, part of the problem? Aaron Wall believes it’s more intentional than inadvertent in his excellent How To Fix The Broken Link Graph post.

Should Google Shut Up?

Shut Up Google

Google has always been somewhat opaque in how it discusses the algorithm and the signals that comprise it. However, they are trying to be better communicators over the last few years. Numerous blogs, videos and Webmaster Central tools all show a desire to give people better guidance.

You’ll still run into stonewalls during panel Q&A, but more information seems to be flowing out of the Googleplex. On the one hand, I very much appreciate that, but a part of me wonders if it’s a good thing.

In this case, the observer is clearly acting on the system.

Should Google tell us meta keywords are really dead? Or that they don’t process Title attributes? Or that domain diversity is really important? Sure, we’ll still have those who postulate about the ranking factors (thank you SEOMoz), but there would be a lot less consensus. It might produce less homogeneity around SEO practices, or in other words, the blur of other signals might lessen if the confidence in signal influence weren’t as clear.

It’s not that the algorithm would change, but perhaps the velocity in which a signal blurs beyond usefulness slows.

The Solution

Well, there really isn’t a solution. A search engine must observe and measure the Internet ecosystem. Acknowledging that they’re part of the system and working on ways to minimize their disturbance of the system would be a good start. Hey, perhaps Google already does this.

The number of signals (more than 200) may be a reaction to the blur produced by their measurement. More signals mean a distribution of blur? But I somehow doubt it’s as easy as a checks and balances system.

Google could maintain very different algorithms – 2 or even 3 – and randomly present them via their numerous data centers. However, they’d all have to provide a good user experience and it’s been difficult for Google to maintain just the one thus far.

I don’t have the answer, but I know that the rate in which the system blurs as a result of Google’s observation is increasing. I believe Google must account for this as they refine the algorithm.

What do you think?

Google Caffeine Is Not An Algorithm Change

February 05 2010 // SEO // Comments Off on Google Caffeine Is Not An Algorithm Change

Google Caffeine

There’s still a lot of speculation and conjecture about Google Caffeine. More than a few have analyzed and theorized based on the preview Google provided. Some have even given tips on optimizing for Caffeine. Don’t believe the hype.

The Google Caffeine Myth

Google Caffeine is not an algorithm change. That’s not to say that the results won’t change here and there, but for the most part the actual scoring is unchanged. There are no special techniques or changes needed to address Google Caffeine.

What is Google Caffeine?

Google Caffeine is a re-architect of the entire indexing system for performance. In short, Caffeine:

  • allows Google to crawl and index more pages
  • allows Google to crawl and index pages faster

The result? The indexing data fed into individual signals is more robust and updated more frequently. This might produce some slight changes to results, but only because of the change in data, not in the change in scoring.

In Google terminology, Google Caffeine increases the rate of data refreshes. I recommend you read and listen to what Matt Cutts has to say on the topic. Vanessa Fox was also a voice of reason with her Search Engine Land Google Caffeine review.

Now, in re-architecting the indexing system, not all data structures are 100% compatible. So, some tiny changes have likely been made, but they’re not meant to be algorithmic changes.

Why Ask For Caffeine Feedback?

Google provided the SEO community with access to Caffeine results and asked for feedback. This request was looked upon by many as an indication that this was an algorithm change.

In fact, this request was a type of distributed QA. The goal of the new indexing system is to increase performance but not appreciably change the algorithmic results. Letting a bunch of hyperactive SEOs into the sandbox helped them to identify any flaws to their re-architected code.

Why Re-Architect The Indexing  System?

Most seem to believe the impetus for Caffeine was around real-time search. I’m sure this was factor, but I doubt it was the primary reason. Google could have pulled off real-time search without Caffeine.

The indexing code in use was written ages ago in Internet-time. Since that time, the Internet has grown and changed dramatically. Algorithmic changes and new signals could only go so far in ensuring quality results. If the data set they were using was incomplete or ‘old’, no amount of signal tinkering would have the desired impact. It’s a simple GIGO problem.

Google needed more data to better inform the algorithm. They need to see more of the Internet. More links. More page changes. Any of you who have ego based Google Alert feeds would have noticed a substantial increase in activity over the last month. It’s not that you’re getting more popular (sorry), Google’s just indexing more and doing so faster than ever before.

Caffeine Is The Beginning

The real question should be what will Google do once Caffeine is fully implemented. Once Google gets all of this data, new patterns will emerge and algorithm changes are certain to follow.

How To See Google Analytics Traffic Faster

February 01 2010 // Analytics + SEO // Comments Off on How To See Google Analytics Traffic Faster

Sometimes you want to see your Google Analytics traffic faster. Whether you’re obsessive, impatient, troubleshooting or benchmarking, you might find yourself frustrated with the 3-4 hour time lag, particularly if it’s a site with a decent amount of traffic.

Stop Waiting for Google Analytics Traffic

Here’s a quick and easy tip to see your Google Analytics traffic faster. (Remember, this only works if you’re looking at intraday traffic.)

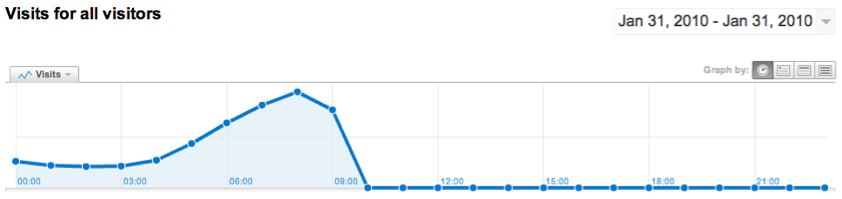
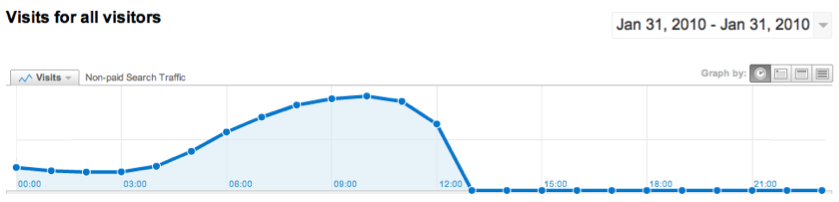
Go to the Visitors > Visitor Trending > Visits report in Google Analytics. Then make sure you’re looking at the graph by hour. The report will look something like this.

Google Analytics Traffic Graph

Now, in the far right select the Advanced Segments drop down and choose one of the default segments. My favorite is Non-paid Search Traffic. Then deselect All Visits so only Non-paid Search Traffic is checked. The result? You get a peek at a few more hours of traffic.

Google Analytics Non-Paid Search Graph

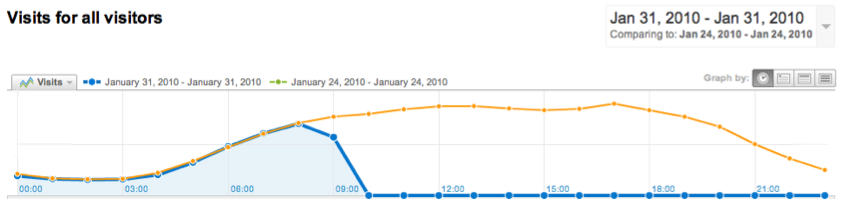
You can leave All Visits on to see the difference between the two if you’re really interested. For me, it’s all about looking at the day’s traffic in comparison to the same day last week. Using the same report with All Visits you get something like this.

Google Analytics All Visits Comparison Graph

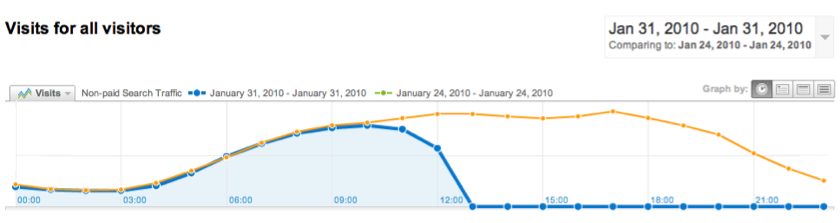
Look at just Non-paid Search Traffic and you get to see those most recent hours. This is the report if you’re serious about SEO.

Google Analytics Non Paid Search Graph Comparison

You can use any of the default advanced segments and can usually use any custom advanced segment that produces enough traffic. So stop refreshing your dashboard stats again and again without success. Instead, follows these few steps and get ahead of the curve.

Yelp robots.txt

January 16 2010 // Humor + SEO // Comments Off on Yelp robots.txt

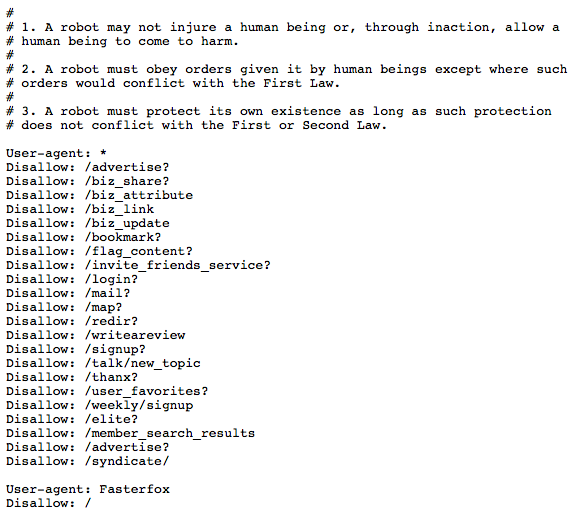
The other day I was doing some robots.txt research and found a great little Easter egg on Yelp.

Yelp Robots.txt

A robots.txt file is a great place to drop Asimov’s Three Laws of Robotics. Thanks for the chuckle Yelp!

2010 Internet, SEO and Technology Predictions

January 03 2010 // Advertising + Marketing + SEO + Social Media + Technology // 5 Comments

As we begin 2010, it’s time for me to go on the record with some predictions. A review of my 2009 predictions shows a few hits, a couple of half-credits and a few more misses. Then again, many of my predictions were pretty bold.

2010 Technology Predictions

This year is no different.

The Link Bubble Pops

At some point in 2010, the link bubble will pop. Google will be forced to address rising link abuse and neutralize billions of links. This will be the largest change in the Google algorithm in many years, disrupting individual SEO strategies as well as larger link based models such as Demand Media.

Twitter Finds a Revenue Model

As 2010 wears on Twitter will find and announce a revenue model. I don’t know what it will be and I’m unsure it will work, but I can’t see Twitter waving their hands for yet another year. Time to walk the walk Twitter.

Google Search Interface Changes

We’ve already seen the search mode test that should help users navigate and refine search results. However, I suspect this is just the beginning and not the end. The rapid rate of iteration by the Google team makes me believe we could see something as radical as LazyFeed’s new UI or the New York Times Skimmer.

Behavioral Targeting Accelerates

Government and privacy groups continue to rage against behavioral targeting (BT), seeing it as some Orwellian advertising machine hell bent on destroying the world. Yet, behavioral targeting works and savvy marketers will win against these largely ineffectual groups and general consumer apathy. Ask people if they want targeted ads and they say no, show them targeted ads and they click.

Google Launches gBooks

The settlement between Google, the Authors Guild and the Association of American Publishers will (finally) be granted final approval and then the fireworks will really start. That’s right, the settlement brouhaha was the warm up act. Look for Google to launch an iTunes like store (aka gBooks) that will be the latest in the least talked about war on the Internet: Google vs. Amazon.

RSS Reader Usage Surges

What, isn’t RSS dead? Well, Marshall Kirkpatrick doesn’t seem to think so and Louis Gray doesn’t either. I’ll side with Marshall and Louis on this one. While I still believe marketing is the biggest problem surrounding RSS readers, advancements like LazyFeed and Fever make me think the product could also advance. I’m still waiting for Google to provide their reader as a while label solution for eTailers fed up with email overhead.

Transparent Traffic Measurement Arrives

Publishers and advertisers are tired of ballpark figures or trends which are directionally accurate. Between Google Analytics and Quantcast people now expect a certain level of specificity. Even comScore is transitioning to beacon based measurement. Panel based traffic measurement will recede, replaced by transparent beacon based measurement … and there was much rejoicing.

Video Turns a Profit

Online video adoption rates have soared and more and more premium content is readily available. Early adopters bemoan the influx of advertising units, trying to convince themselves and others that people won’t put up with it. But they will. Like it or not, the vast majority of people are used to this form of advertising and this is the year it pays off.

Chrome Grabs 15% of Browser Market

Depending on who you believe, Chrome has already surpassed Safari. And this was before Chrome was available for Mac. That alone isn’t going to get Chrome to 15%. But you recall the Google ‘What’s a Browser?‘ video, right? Google will disrupt browser inertia through a combination of user disorientation and brand equity. Look for increased advertising and bundling of Chrome in 2010.

Real Time Search Jumps the Shark

2009 was, in many ways, the year of real time search. It was the brand new shiny toy for the Internati. Nearly everyone I meet thinks real time search is transformational. But is it really?

A Jonathan Mendez post titled Misguided Notions: A Study of Value Creation in Real-Time Search challenges this assumption. A recent QuadsZilla post also exposes a real time search vulnerability. The limited query set and influx of spam will reduce real time search to an interesting, though still valuable, add-on. The Internati? They’ll find something else shiny.

The Link Bubble

December 28 2009 // SEO // 6 Comments

The real estate bubble popped. Will the link bubble be next?

Link Bubble

The real estate bubble was the product of greed, low interest rates, loose lending policies and derivatives. Nearly anyone could get a house and people bought into the idea that real estate would always be a good investment. The result of this irrational exuberance? Homes were valued far more then they were worth.

The Link Bubble

Are links that different than real estate?

Links have traditionally been a reliable sign of trust and authority because they were given out judiciously, a lot like mortgages. For a long time link policies were tight. You needed references and documentation before you earned that link.

In addition, links weren’t looked upon as an investment tool. The concept that links influenced SEO hadn’t taken hold. The motivation behind links was relatively pure and that meant Google and others could rely on them as an accurate signal of quality.

Links or Content?

Many have recently bemoaned the death of hand crafted content and the rise of content farms as a threat to search quality. But is content really the problem?

Content has little innate value from a search perspective. Yes, search engines glean the content topic based on the text. It’s like knowing the street address of a house. You know where it is and, probably, a bit about the neighborhood. But it doesn’t tell you about the size, style or quality of the home.

Long tail searches are akin to searching for a house by street address. So, content without links may sometimes produce results. But the vast majority of searches will require more information. That’s where links come in.

McDonald’s Content

Lets switch analogies for a moment. Some have called Demand Media the McDonald’s of content. There’s a bit of brilliance in that comparison, but not in the way most think.

Both McDonald’s and Demand Media crank out product that many would argue is mediocre. Offline, McDonald’s buys the best real estate and uses low prices, brand equity and marketing to ensure diners select them over competitors.

Online, Google holds the prime real estate. But that real estate can’t be outright purchased. And in the absence of price, we’re left with brand equity and marketing. Online, brand equity translates into trust and authority. And links are the marketing that help build and maintain that brand equity.

Demand Media has brands (their words) that give it automatic trust and authority. Publish something on eHow and it automatically inherits the domain’s trust and authority, built on over 11 million backlinks.

Writers for Demand Media are provided revenue share opportunities on their articles. Here’s one of the tips they give to writers to boost traffic to their articles.

2) Link to your article from other websites.

Link from your own website or blog, from a message board or forum, from your social networking profile on MySpace or Facebook and more. The more high quality links to your article there are on the web, the more highly a search engine will rank it.

Demand Media combines the installed brand equity of multiple sites (which happen to be cross-linked) with an incentive to contributors to generate additional links. The content doesn’t have to be great when links secure premium online real estate.

There might be something better down the road, but McDonald’s is always right there at the corner.

Link Inflation

The last few years have produced major changes surrounding links. Linkbuilding is now a common term and strategy. A number of notable SEO firms tout links as the way to achieve success.

Linkbuilding firms sprung up. Linkbulding software of various shades of gray were launched. Paid links of various flavors flourished. Social bookmarking and networking accelerated link inflation. And new business models like Demand Media sprung up to take advantage of the link economy, creating a collection of sites and implementing incentives that result in something that resembles derivatives.

Link policies went from tight to loose and people got greedy. Anyone can get links these days. So what’s the natural result of this link activity?

Link Bubble Pops

Link Recession

The value of links is inflated and at some point the system will correct. The algorithm will change to address the abuse of links. Unlike The Federal Reserve, Google probably isn’t looking for a soft landing, nor are they going to extend a bailout.

Some links will continue to matter. Links that are in the right neighborhood. The ones with tree lined streets, good schools and low crime. But will links from cookie cutter planned communities still be valuable? Strong links will mean more because they’ll hold their value, while many more links will be neutralized.

I’m no Nouriel Roubini, but I do believe that a major link correction is coming in 2010. Google must address the link bubble to make search results better.

Google Brand Search Results

December 15 2009 // SEO // Comments Off on Google Brand Search Results

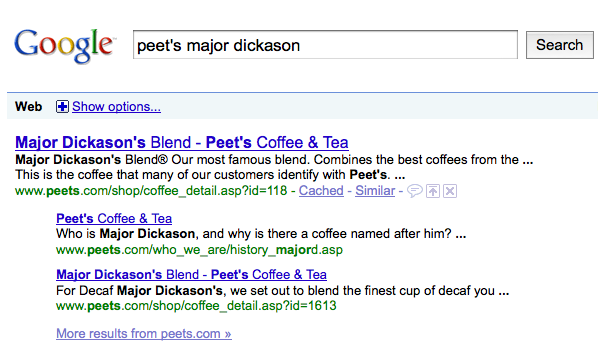
In late October Google launched a new type of search result for brand queries. Noted on Google Blogoscoped, a brand search result takes up an enormous amount of real estate and is composed of one regular listing and two indented listings.

When are brand search results shown?

The brand result is only triggered by certain queries. Oddly, it’s not just a brand name. Instead, it’s a brand name coupled with another keyword or keywords.

So, a search for ‘Peet’s’ will not trigger a brand result. But a search for ‘Peet’s Major Dickason’ will.

Google Brand Result

Is it really about brands?

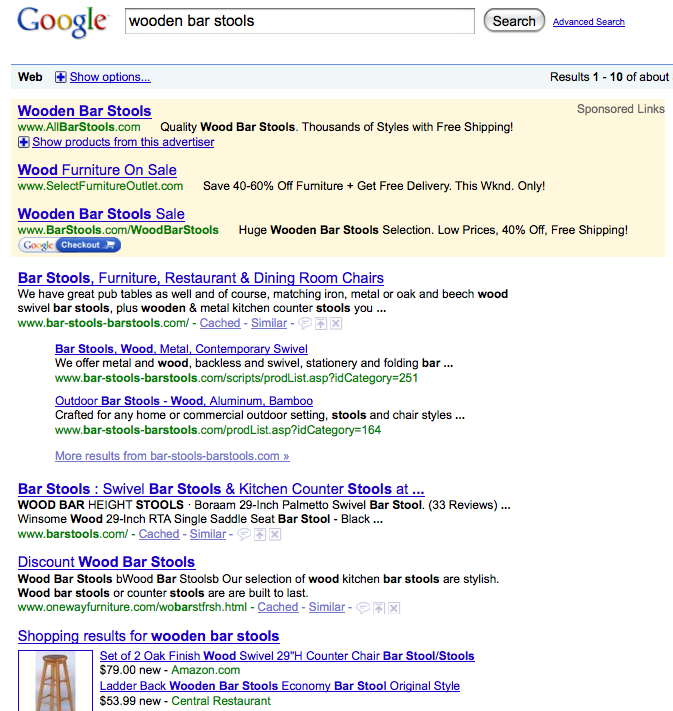
Upon the launch of this new result it seemed like it was solely a function of what was in the domain. A search for ‘wooden bar stools’ triggered the new result.

Google Brand Result

Here, the domain of bar-stools-barstools.com triggered the new result when it matched the ‘brand + modifier’ query. A simple domain match against the keyword query, right?

Yet, when you search on this same term today you don’t get the new brand result.

Google wooden bar stools query

So what started as a simple domain match has evolved into something more refined. This isn’t capricious in nature. Google is always looking for ways to improve search quality. In this scenario they have weighted the actual brand or company site as more authoritative for a fairly large set of ‘brand + modifier’ queries.

What’s the criteria for Google brand search results?

How Google is doing this refinement is unclear. Some have surmised Google is using some sort of brand database or that it’s related to their DNS service.

I tend to believe there was some sort of initial criteria (broad in nature) for this new brand result with a built-in refinement mechanism. The refinement would be accomplished through analysis of user behavior on these results (e.g. – relative CTR and length of clicks), SearchWiki data or human editing.

User behavior might be difficult to mine since the large amount of real estate brand results take up likely make them click magnets. And click length might describe the value and quality of the site but not whether it merits the brand result presentation.

SearchWiki data and human editing are essentially the same concept, with the former being accomplished by a decentralized group of users (the proverbial cloud) and the latter being done by a centralized group of Google employees. Human editing doesn’t seem that far-fetched to me, particularly if Google used user behavior or SearchWiki data to identify domains for review. The result would be an easy and efficient review queue.

Why is Google interested in brands?

No matter how Google is doing it, the fact that they are is a signal that brands and companies provide a new proxy for trust and authority. The first step in this direction was the Vince change which unseated many highly optimized sites from root terms and replaced them with relevant brands or companies.

The current algorithm continues to struggle with trust and authority with 0ver-optimization reducing the value of on-page factors and the rise of link pollution quickly eroding the value of off-page factors.

Google brand search results show a continuing interest in moving beyond current signals to improve search quality and deliver better results. So while the new brand search result went largely unreported, it could be a harbinger of a larger algorithmic shift in 2010.

Google Search Innovation Accelerates

October 27 2009 // SEO // Comments Off on Google Search Innovation Accelerates

It’s not your imagination. Google’s rate of search innovation has accelerated. Google has marched through shopping Onebox enhancements (9/14), expanded forum listings (9/14), anchor based jump to and site links (9/25), Search Options expansion (10/1), Quick View PDFs (10/7), Twitter integration (10/21) and Social Search (10/26).

You could even include ancillary search innovations like Sidewiki (9/23) and fetch as Googlebot (10/12).

Gooogle Search

It’s been so fast that Google launched a series of weekly blog posts (This Week in Search) to keep up with the changes.

Pent Up Search Innovation?

For the past few years Google has stated in numerous venues that they didn’t particularly want to grow their share of the search market. They explained that extending their market share lead could incur the wrath of government oversight or create user backlash.

The jaded in the audience rolled their eyes and even the purists probably furrowed their brow. Sure, it makes a bit of sense but … really?

Yet, the timing of these recent search innovations is intriguing.

Bing Allows Google To Innovate

Microsoft’s latest dedication to search could be the reason for Google’s recent spate of search enhancements. Before Bing went live Google rolled out rich snippets, making Google last to the rich listings party. The preemptive move secured a certain search parity in the space.

That box checked off, Google sat back and watched as Bing innovated, advertised and finally partnered with Yahoo. Bing’s share began to inch up toward 10% and that seemed to be enough for the search behemoth to release the hounds engineers.

One gets the impression that projects that had once been stashed in a drawer were suddenly taken out, dusted off and quickly deployed.

What else does Google have in store for us?